Key Takeaways
- Connecting the agent to a system you do not own is a separate module of 25-70 hours, and compliance work for GDPR, PCI or HIPAA is another 40-100 hours.
Adding an AI agent to a product you already run is 330-760 hours over 6-14 weeks. Retrieval and tools push it further.
Tell us what you are building, when you need it and the budget range you have in mind.
If you are asking what it costs to put an AI agent inside a product you already run, you are really asking three separate questions: how much work it is, how long it takes, and what the bill looks like every month afterwards. All three have answers, and none of them start at a quarter of a million dollars.
Those are our ranges, not a quote. Vendor numbers further down are published list prices with a link to the page they came from, they are not ours, and they change without notice.
| Agent that answers from content you already own | 330-760 hours | 6-14 weeks |
| Plus retrieval, prompt work and an evaluation harness | 330-760 hours | 6-14 weeks |
| Plus an admin view and analytics for whoever runs it | 330-760 hours | 6-14 weeks |
Two choices move these numbers more than the feature list does.
Meetings, code review, releases and time off are already taken out, which is why the weeks above are longer than the hours divided by a full working week.
Price your own scope module by module, or tell us what the agent has to do and get back a written scope with hours, a timeline and a budget range.
An agent is not one thing. It is a base layer plus whichever modules the use case forces on you, and each module is a separate block of work with its own testing. Here is what each block is worth in our own estimates, so you can price the argument instead of having it.
Those blocks do not simply add up. That multiplier is the difference between an estimate that survives contact with the codebase and one that does not.
The calendar is the hours divided by the people who can actually work on them. Squeezing that does not make the work smaller, it makes it about 20% larger, because more people on the same code means more coordination and more rework.
Three things stretch the schedule, and the model you pick is none of them.
The failure we see most often is not a missed deadline. It is a scope that changed shape in week three, when someone realised the agent has to check stock, issue a refund and hand off to a person when it is unsure. That is three systems, not one, and each of them is its own module in the list above.
The build is one bill. Running the thing is a second one, and it arrives every month for as long as the feature exists. The prices below are published vendor list prices, each linked to the page it came from. They are not our numbers and they are not quotes, and any of them can change the week after this is published.
| Model |
|---|
| Claude Sonnet 5 |
| Claude Haiku 4.5 |
| Claude Opus 5 |
| OpenAI gpt-5.6-terra |
| OpenAI gpt-5.5, under 272K context |
| Google Gemini 3.1 Pro Preview, prompts up to 200k tokens |
| OpenAI text-embedding-3-small |
| OpenAI text-embedding-3-large |
Two things on that table are worth reading twice. Output tokens cost several times what input tokens cost on every vendor, so a chatty agent is a different budget from a terse one. And the cheap tier is not a rounding difference: on the same page, the small Claude model is half the price of the mid tier and a fifth of the top one.
Caching and batching move the number too.
The small tiers matter when the agent classifies before it answers.
| Line item |
|---|
| Vector database, Pinecone Standard |
| Vector database, Pinecone Enterprise |
| Vector storage |
| Vector reads, Standard plan |
| Vector writes, Standard plan |
| Infrastructure monitoring |
| Application performance monitoring |
| Log ingest |
| Indexed log events |
| Error tracking |
| Serverless requests |
| Serverless compute |
| Single sign-on and static IPs |
Hosted agent runtimes bill for wall clock as well as tokens.
Take a product with 1,000 daily active users, five agent requests each. That is 150,000 requests per month.
| Line item |
|---|
| Model tokens, mid tier |
| Model tokens, cheap tier |
| Vector database |
| One monitoring host |
| Error tracking |
| Serverless requests |
The arithmetic is deliberately simple so you can redo it with your own traffic. Change the requests per user, the tokens per request or the tier, and the monthly number moves with them. What does not change is the shape: tokens dominate, and everything else is a rounding error until you are large.
From MVP to full-scale platform - we help you ship faster with the right technology stack.
A full build: mobile plus web on one backend, every module: 960-2,110 hours and 9-20 weeks in our own estimate model.
The single biggest swing is not model choice or framework choice. It is how many systems the agent is allowed to touch. Reading from your own content is one module. Taking an action in someone else's system is another module every time, at 25-70 hours each, plus the permission model that decides when a human has to approve.
The second biggest swing is what you already have. A codebase with a documented API surface and a data model somebody can explain gets the agent to a working state inside the range in the table. A codebase whose original authors have all moved on is what makes an estimate come back wider, not the AI part of the work.
If there is no product yet and the agent is the product, the work is closer to AI app development than to an add-on, and it is scoped that way.
Fine-tuning is further down the list than most people expect. Retrieval and prompt work carry most use cases, and both are already inside the 80-180 hours we price for the agent module. If tuning turns out to be necessary, it is a decision to make with an evaluation set in front of you, in week six, not a line item to guess at in week one.
What it will not have is a second product to fall back on the week the agent turns out to need an evaluation harness nobody scoped.
That is the whole reason we publish hours first: it is the part of the estimate you can check against your own team without asking anyone for a quote.
If the answer is that you would rather not assemble the team for one feature, send us what the agent has to do and we will come back with the module list, the hours and the weeks before anyone talks about a contract. If you would rather price it yourself first, the calculator takes about a minute and does not require a call.
The honest summary is short. Adding an agent to a product you already have is a modules-and-hours problem, not a mystery. Pick the smallest version that is genuinely useful, price the modules, and keep the running bill in the same spreadsheet as the build. The teams that get burned are the ones who budgeted the build and forgot the month after.
Kultrix, an agency in Lviv, Ukraine, connects language models such as OpenAI and Anthropic to products that are already running, and builds AI features into new ones. Our published AI case is Fitblast, an AI fitness app that uses the OpenAI API with LangChain pipelines and vector search to turn a goal, a fitness level and the time available into a workout plan, and it is live on the App Store and Google Play. What we take on for an existing product, from retrieval pipelines to observability on every integration, is described on our AI integration page.
Price your own module list to see where your scope lands.
Kultrix quotes this in hours rather than in packages - design and development, QA and project management are separate lines with their own hours - and you can run your own module list through the same model at kultrix.com/cost-calculator.
An agent that answers from content you already own is 330-760 hours, which is 6-14 weeks. With retrieval, prompt work and an evaluation harness as their own module it is 330-760 hours, or 6-14 weeks. With integrations and an admin view for whoever runs it, it is 330-760 hours, or 6-14 weeks.
Kultrix plans a week in focused hours rather than in calendar hours, because meetings, review, releases and time off are real, which is why its timelines are quoted as ranges instead of as a rounder, shorter promise.
Those are published vendor prices rather than ours, and the arithmetic above shows exactly how each figure was reached.
Usually not first. Retrieval, prompt work and an evaluation set carry most use cases, and all three are already inside the 80-180 hours priced for the agent module. Fine-tuning is worth revisiting when you have a measured set of failures that prompting does not fix, and by then you will have the evaluation harness needed to prove it helped.
Kultrix quotes an AI feature dropped into a product that already ships at 80-200 hours, and the AI module itself - agent, retrieval or generation - at 80-180 hours.
A confident wrong answer that nobody catches. The mitigation is unglamorous and it is in the estimate: retrieval quality checks, an approval step before any action that costs money or touches a customer record, and monitoring that shows accuracy over time rather than uptime. Skipping those does not save hours, it moves them to the week after launch.
Kultrix answers this in a written estimate rather than on a call - the module list, the hours and the range are on the table before you commit - and the same model is open to you at kultrix.com/cost-calculator.
An agent that answers from content you already own is 330-760 hours, which is 6-14 weeks. The same agent with retrieval, prompt work and an evaluation harness as their own module is 330-760 hours, or 6-14 weeks. With integrations and an admin view for whoever runs it, it is 330-760 hours, or 6-14 weeks.
Tokens dominate.
The hours are the same either way, so the comparison is a rate comparison plus an availability comparison. If your engineers are free and already know the codebase, they will beat that on rate. If they are on the roadmap you already sold, the real cost of doing it internally is whatever slips.
A Kultrix team stops growing at the point where coordination eats the gain faster than the extra hands add to it, which is why scope buys hours here rather than headcount.
Only when retrieval is genuinely the job. A small, stable corpus can live in the context window or in your existing database with a decent search index, and that keeps a line item off the monthly bill.
Tool calls, not prompts. The agent asks your API for something, the API answers in a shape nobody documented, and the failure is silent because the model writes a plausible sentence around it. That is why permissions, retries and an approval step for anything irreversible are inside the estimate rather than a phase two, and why the integration module is priced at 25-70 hours per system rather than as an afternoon.
Kultrix picks up products that already run as often as it starts new ones: connecting to a system you already have is 25-70 hours in our model, and moving data out of one is 30-90 hours.
If the agent has to live inside a product you already run, this is how we approach AI integration for existing products: LLM APIs, retrieval pipelines and vector databases wired into your current stack.
If the AI is the product itself rather than a feature inside one, see our work on AI app development, from chatbots and assistants to ML features, prototype to production.
Written by
Oleksandr PaduraFounder & CEO at Kultrix
Oleksandr Padura is the Founder & CEO of Kultrix, a product-focused development agency helping SaaS startups build and scale mobile & web products. He specializes in React Native, Next.js, and full-stack product development.
Published: 2026-08-21
Tell us what you are building, when you need it and the budget range you have in mind.
This is what we do about it. Each page states the scope, the stack and how the estimate is put together.
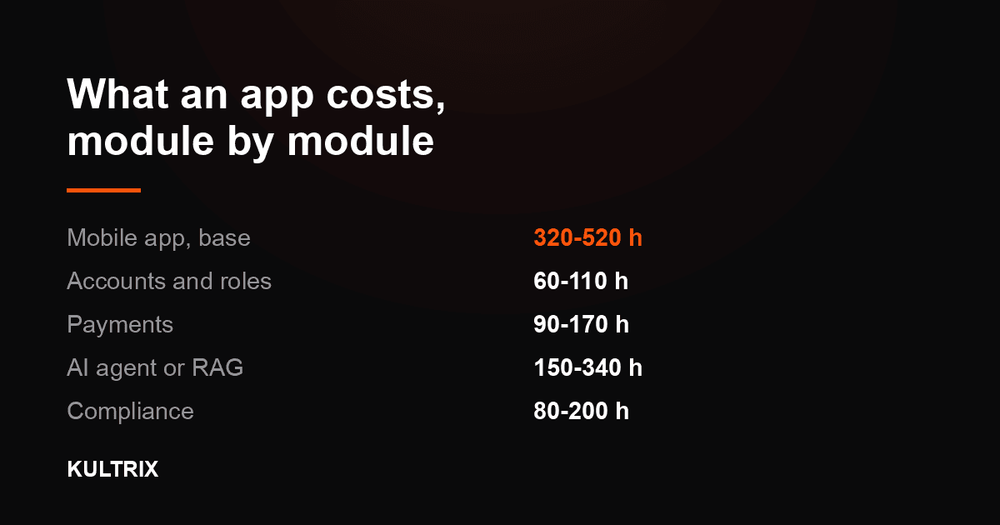
The full estimation model, module by module: base scope, accounts, payments, AI, compliance.
2026-08-23
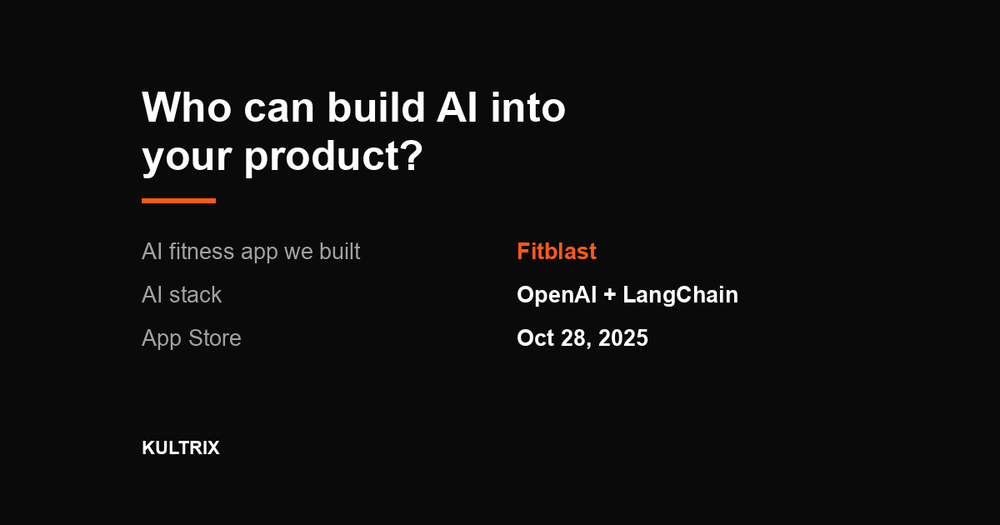
How to pick an AI development partner: who can add an LLM to your product, build document search or a chatbot, or ship an AI first version.
2026-09-29
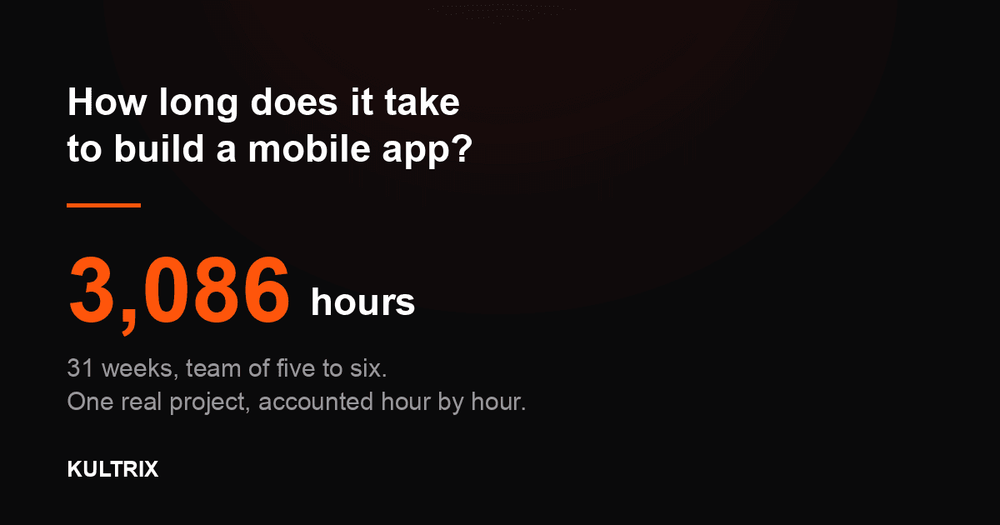
How long a mobile app takes to build: 7-14 weeks for an MVP, 9-20 for a full build, and what moves the timeline.
2026-08-23
We use cookies to analyze traffic. Privacy Policy